AWS SQS Outage: Causes, Impact, and How to Protect Your Apps
On a recent day in late 2023, many developers woke to a silent storm: the AWS Simple Queue Service (SQS) was down. The incident, dubbed the AWS SQS outage, left distributed systems scrambling to keep messages flowing. In this quick read, we unpack what triggered the disruption, how it affected services, and, most importantly, the steps you can take to keep your applications humming even when SQS stutters.
AWS SQS outage: What Went Wrong
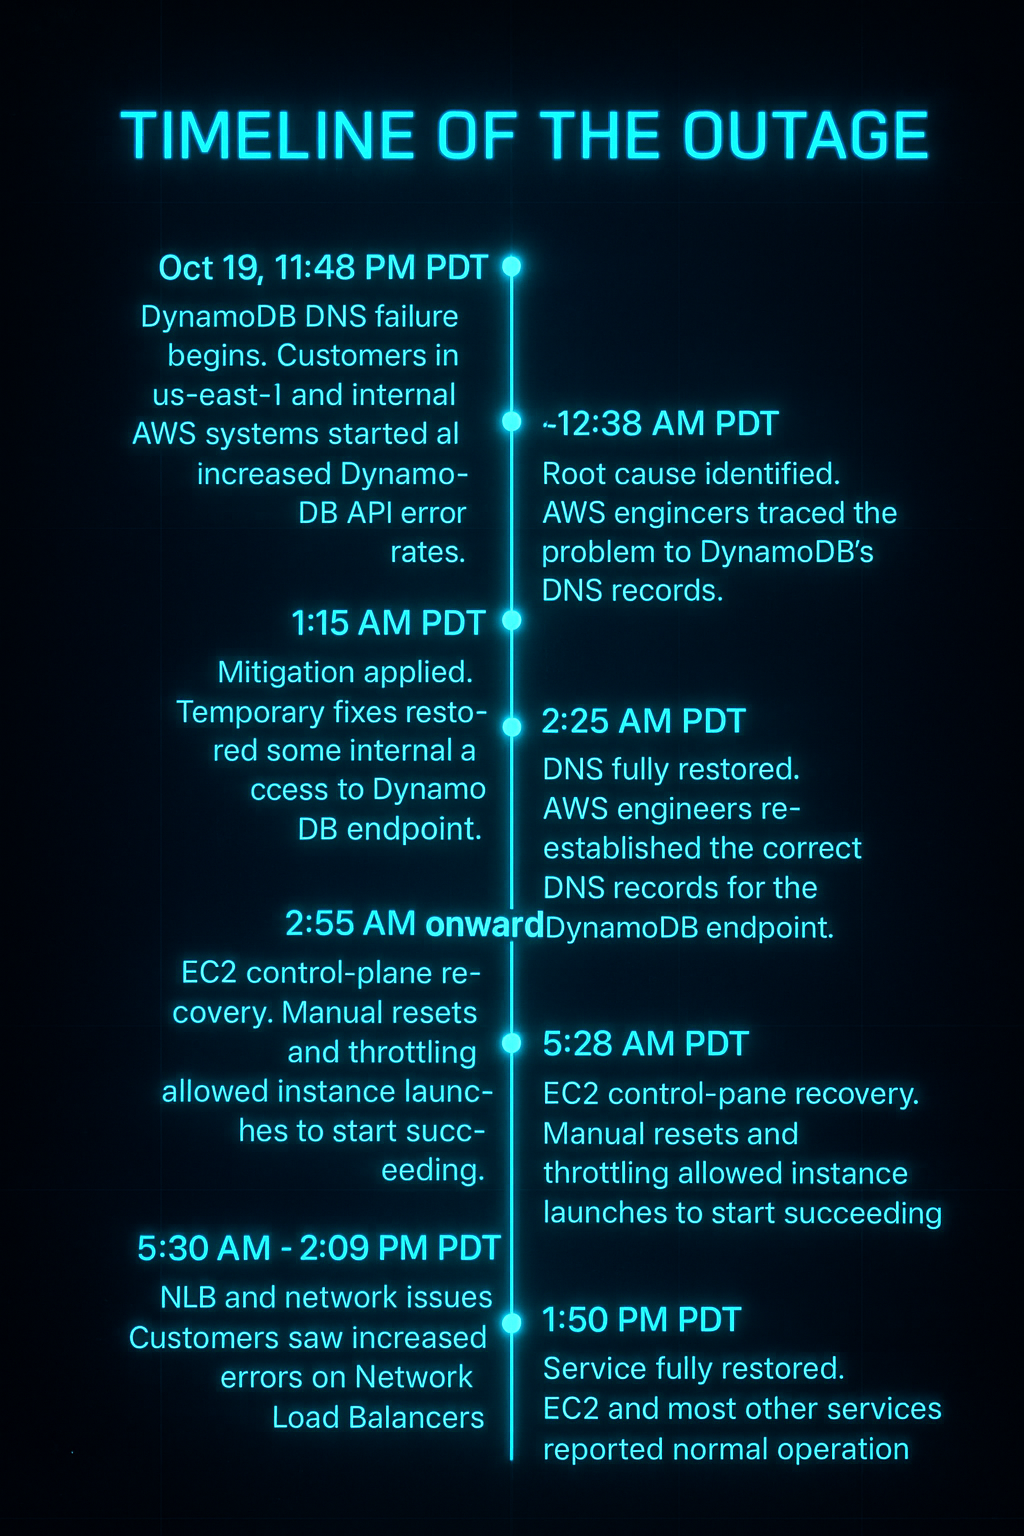
When the outage began, users across the us-east‑1 region reported latency spikes and eventual timeouts. AWS’s status page listed the incident as “regional service disruption” and attributed the root cause to a software bug within the SQS queue replication logic. While AWS has not released a detailed post‑mortem, the incident highlights a key lesson: even a single component in a highly available architecture can become a single point of failure if not protected.
Why the Outage Happened
- Replication glitch: SQS replicates queue state across multiple availability zones. A bug in that replication step left queues in an inconsistent state.
- Network routing issue: Some customers experienced misdirected traffic, causing requests to hit an unresponsive node.
- Insufficient auto‑scale: The SQS service was unable to scale its worker pool quickly enough to absorb the sudden surge in retries.
Regardless of the precise trigger, the outage underscored that a cloud service’s advertised availability is not a guarantee against all failure modes.
Impact on Your Services
When SQS stalls, the downstream effects can ripple quickly:
- Processing delays: Consumer applications waiting on messages experience timeouts, leading to increased latency.
- Message loss: Although SQS offers at‑least‑once delivery, a sudden shutdown can cause some messages to be stuck in transit or lost if not retried.
- Back‑pressure on downstream systems: Producers may block on
SendMessagecalls, choking the entire pipeline.
In practice, teams observed higher error rates in logging, increased CPU usage on worker nodes, and in some cases, a cascading failure that shut down dependent services like databases or API gateways.
Steps to Prepare for Future Disruptions
Designing with resilience in mind means you’ll be less surprised by the next hiccup. Consider the following layers of defense:
1. Multi‑Region Queues
Deploy parallel SQS queues in a secondary region and use Cross‑Region Replication (via SendMessageBatch with QueueUrl from the backup region). If one region goes down, the application can switch to the other with minimal code changes.
2. Dead‑Letter Queues (DLQs) for Early Detection
Configure a DLQ with a generous VisibilityTimeout and MaximumMessageRetentionPeriod