Cloud‑Native Tech in Action: Real‑World Success Stories
When most developers hear “cloud native,” the image that comes to mind is a maze of containers, microservices, and continuous delivery pipelines. Yet behind those buzzwords lie concrete examples of companies reshaping their businesses by embracing cloud‑native technology. In this article we’ll unpack how firms from entertainment to finance to science are using Kubernetes, serverless functions, GitOps, and more to stay nimble, scale fast, and innovate. If you’re curious how these tools translate to real revenue gains or faster time‑to‑market, keep reading.
What Does “Cloud‑Native Technology Real‑World Examples” Mean?
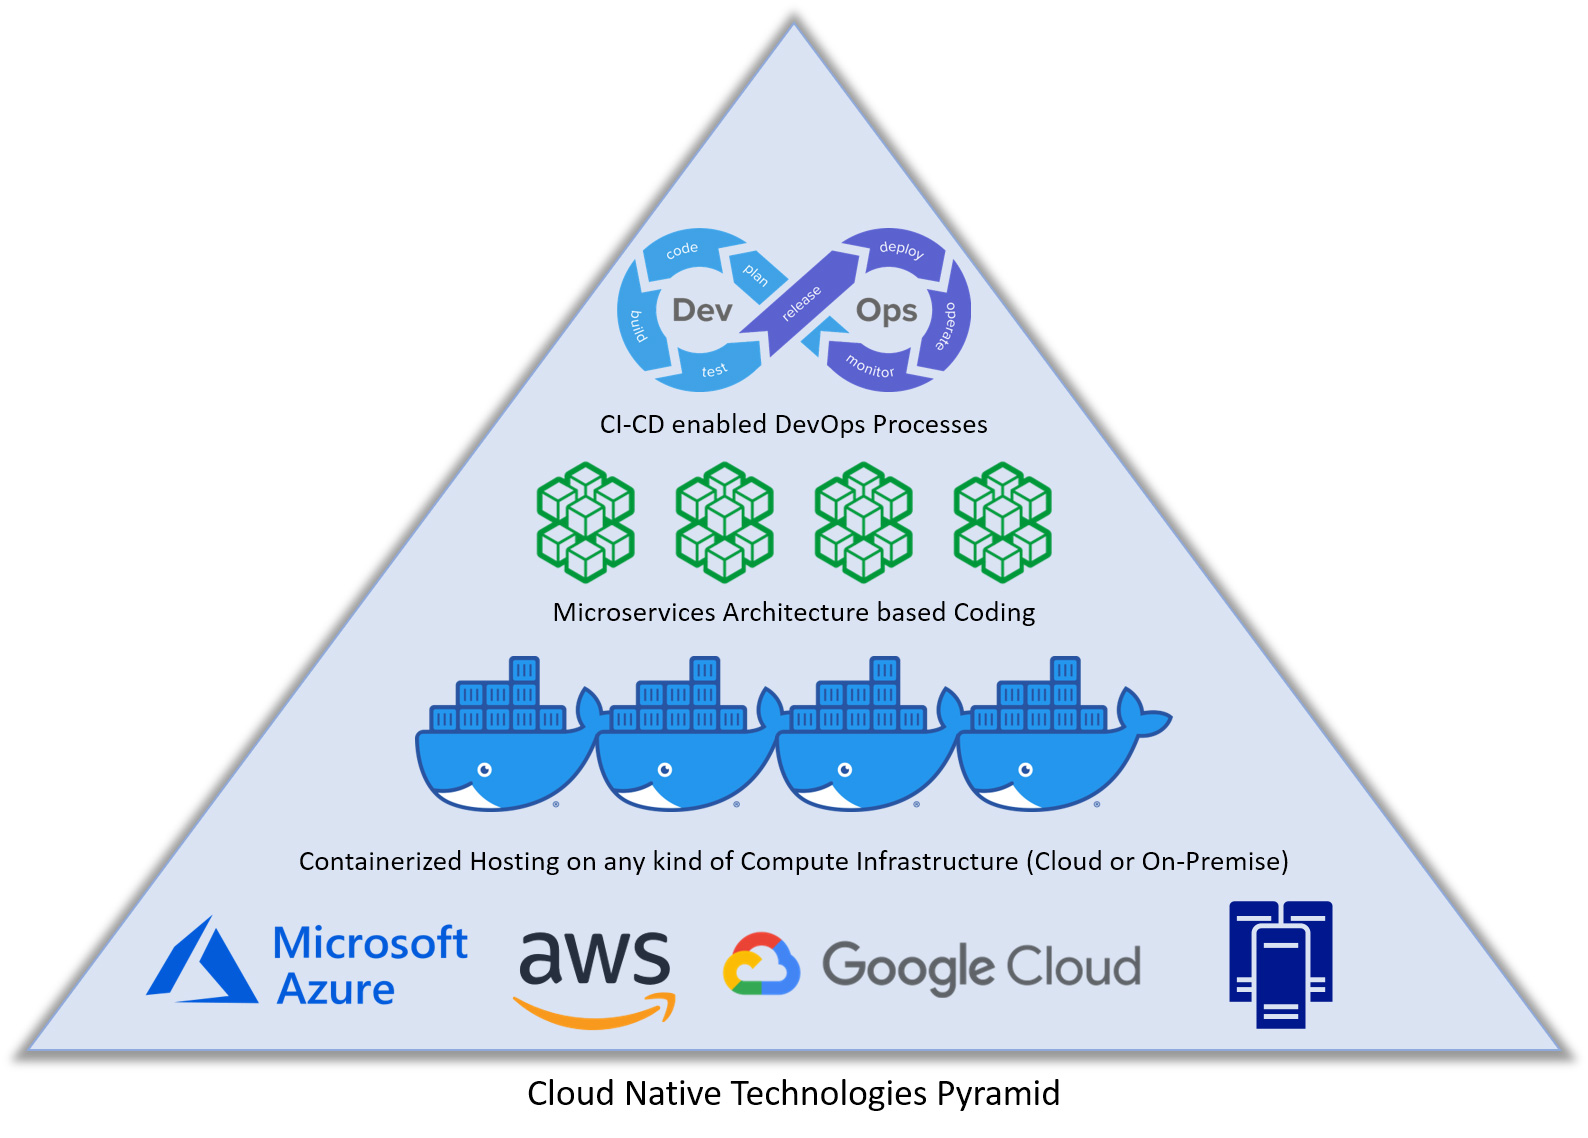
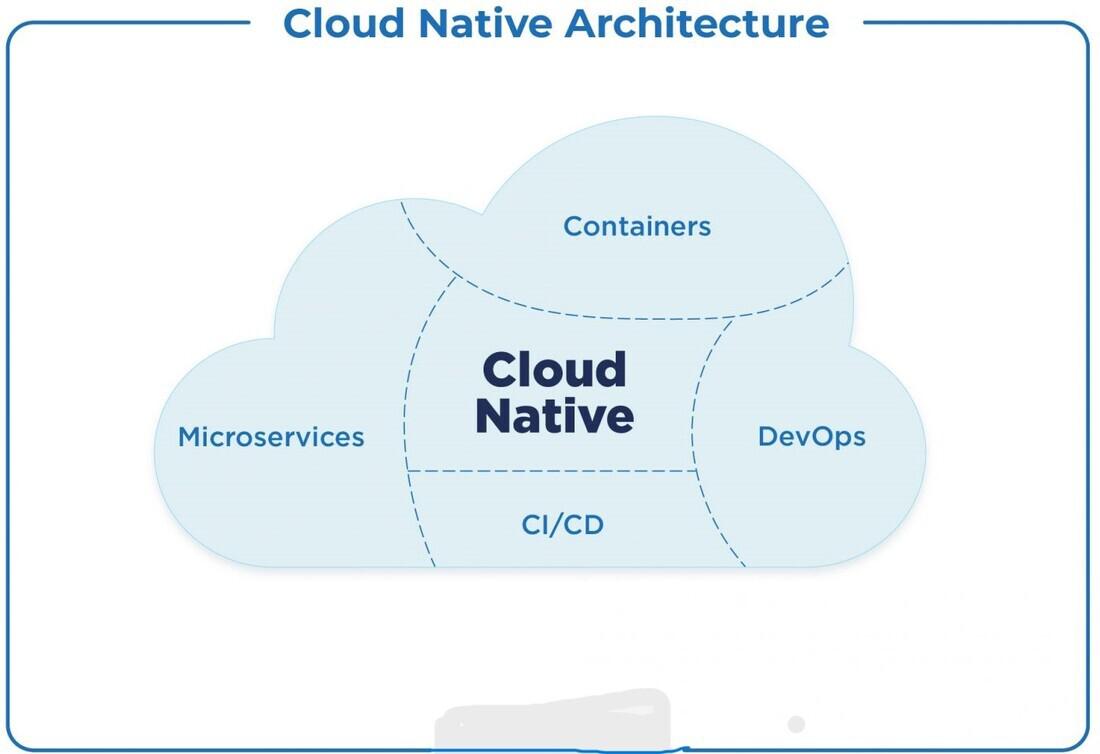
Cloud‑native refers to designing applications that fully leverage the flexibility and elasticity of cloud environments. Key principles include containerization, declarative APIs, immutable infrastructure, and automation. When we talk about real‑world examples, we mean documented deployments where these principles have produced measurable outcomes—speed, resilience, cost savings, or new product features.
Kubernetes: The Operating System of the Cloud
Since its open‑source launch by Google, Kubernetes has become the default orchestrator for microservices. Netflix’s Spinnaker pipeline, for instance, runs on Kubernetes clusters that span multiple regions, automatically rolling out feature flags while keeping user traffic uninterrupted. In 2023, Netflix reported that 60% of its new microservices were deployed in Kubernetes, reducing deployment time from weeks to hours.
Another illustration comes from Shopify. The e‑commerce platform migrated over 70% of its services to Kubernetes, achieving a 40% reduction in infrastructure spend and enabling rapid experimentation with new checkout flows.
Serverless Function Platforms: Instant Scalability
Serverless frameworks such as AWS Lambda, Azure Functions, and Google Cloud Functions let developers ship code without managing servers. Capital One turned a legacy fraud‑detection system into a set of Lambda functions, cutting latency by 30% and lowering operational overhead. Meanwhile, Spotify uses Google Cloud Functions to process user playlists in real time, scaling to millions of concurrent requests during new feature rollouts.
Event‑Driven Architecture with Kafka and Knative
Companies are coupling serverless with event streaming to handle bursty workloads. Airbnb runs a Kafka cluster on Kubernetes, feeding events into Knative services that auto‑scale to zero when idle, saving on compute costs. This pattern allows Airbnb to process over 300 million events per day with consistent response times.
GitOps: Version Control as the Single Source of Truth
GitOps brings declarative infrastructure into a familiar Git workflow. Red Hat OpenShift uses GitOps to deploy applications across on‑prem and cloud environments, ensuring that any change in a branch automatically propagates to the target cluster after automated testing. CERN adopted GitOps with ArgoCD to manage its high‑throughput data pipelines, reducing deployment failures by 70%.
Infrastructure as Code: Terraform, Pulumi, and Cloud Native Buildpacks
Infrastructure as Code (IaC) lets teams treat cloud resources like software. eBay migrated its staging environments to Terraform modules, enabling quick spin‑up of replicas for load testing. GitHub uses Pulumi to manage its multi‑cloud resources, allowing teams to write IaC in familiar languages like TypeScript.
Cloud Native Buildpacks, introduced by the Cloud Native Computing Foundation, convert application source into container images without manual Dockerfiles. Heroku integrated Buildpacks to give developers instant, optimized images, cutting build times from minutes to seconds.
Observability: Monitoring, Logging, and Tracing in the Cloud
Observability is critical in a distributed microservice landscape. Netflix built its own open‑source observability stack—OpenTelemetry, Prometheus, and Grafana—to monitor 10,000+ services worldwide. The result? A 25% reduction in mean time to resolution for production incidents.
Similarly, Shopify uses distributed tracing to pinpoint latency spikes across its checkout flow, leading to a 15% increase in conversion rates after optimizing critical service paths.
Case Study: CERN’s High‑Performance Computing on Kubernetes
The European Organization for Nuclear Research (CERN) faced the challenge of processing petabytes of data from the Large Hadron Collider. By migrating to a Kubernetes‑based architecture on Google Cloud, CERN achieved near‑real‑time data analysis, cutting processing times from days to hours. The elastic nature of Kubernetes also allowed CERN to scale up for peak data influx during major experiments, without overprovisioning resources.
Benefits Summarized in Numbers
- Deployment speed: From weeks to minutes
- Cost savings: 30–50% in compute spend for many enterprises
- Reliability: 99.99% uptime for services that auto‑heal
- Innovation velocity: Faster time‑to‑market for new features and experiments
FAQs
Q: What’s the biggest risk when adopting cloud‑native tech?
A: The learning curve and cultural shift. Teams need to embrace automation, declarative configs, and a DevOps mindset to realize benefits.
Q: Do I need a dedicated team for Kubernetes?
A: Not necessarily. Many managed services like Google Kubernetes Engine or Azure AKS handle cluster operations, allowing developers to focus on application logic.
Q: Can small startups benefit from these practices?
A: Absolutely. Serverless functions and GitOps can reduce operational overhead for startups, freeing resources for product development.