How List Crawlers Supercharge Real‑Time Analytics
When businesses chase the next instant insight, they often overlook a surprisingly simple tool: the list crawler. Unlike heavyweight web spiders that sweep entire sites, list crawlers focus on targeted collections—think product catalogs, price sheets, or public APIs—delivering fresh data exactly where it matters. In a world where minutes can mean millions, leveraging these focused harvesters can turn raw feeds into actionable intelligence faster than you’d expect.
What Makes a List Crawler Different?
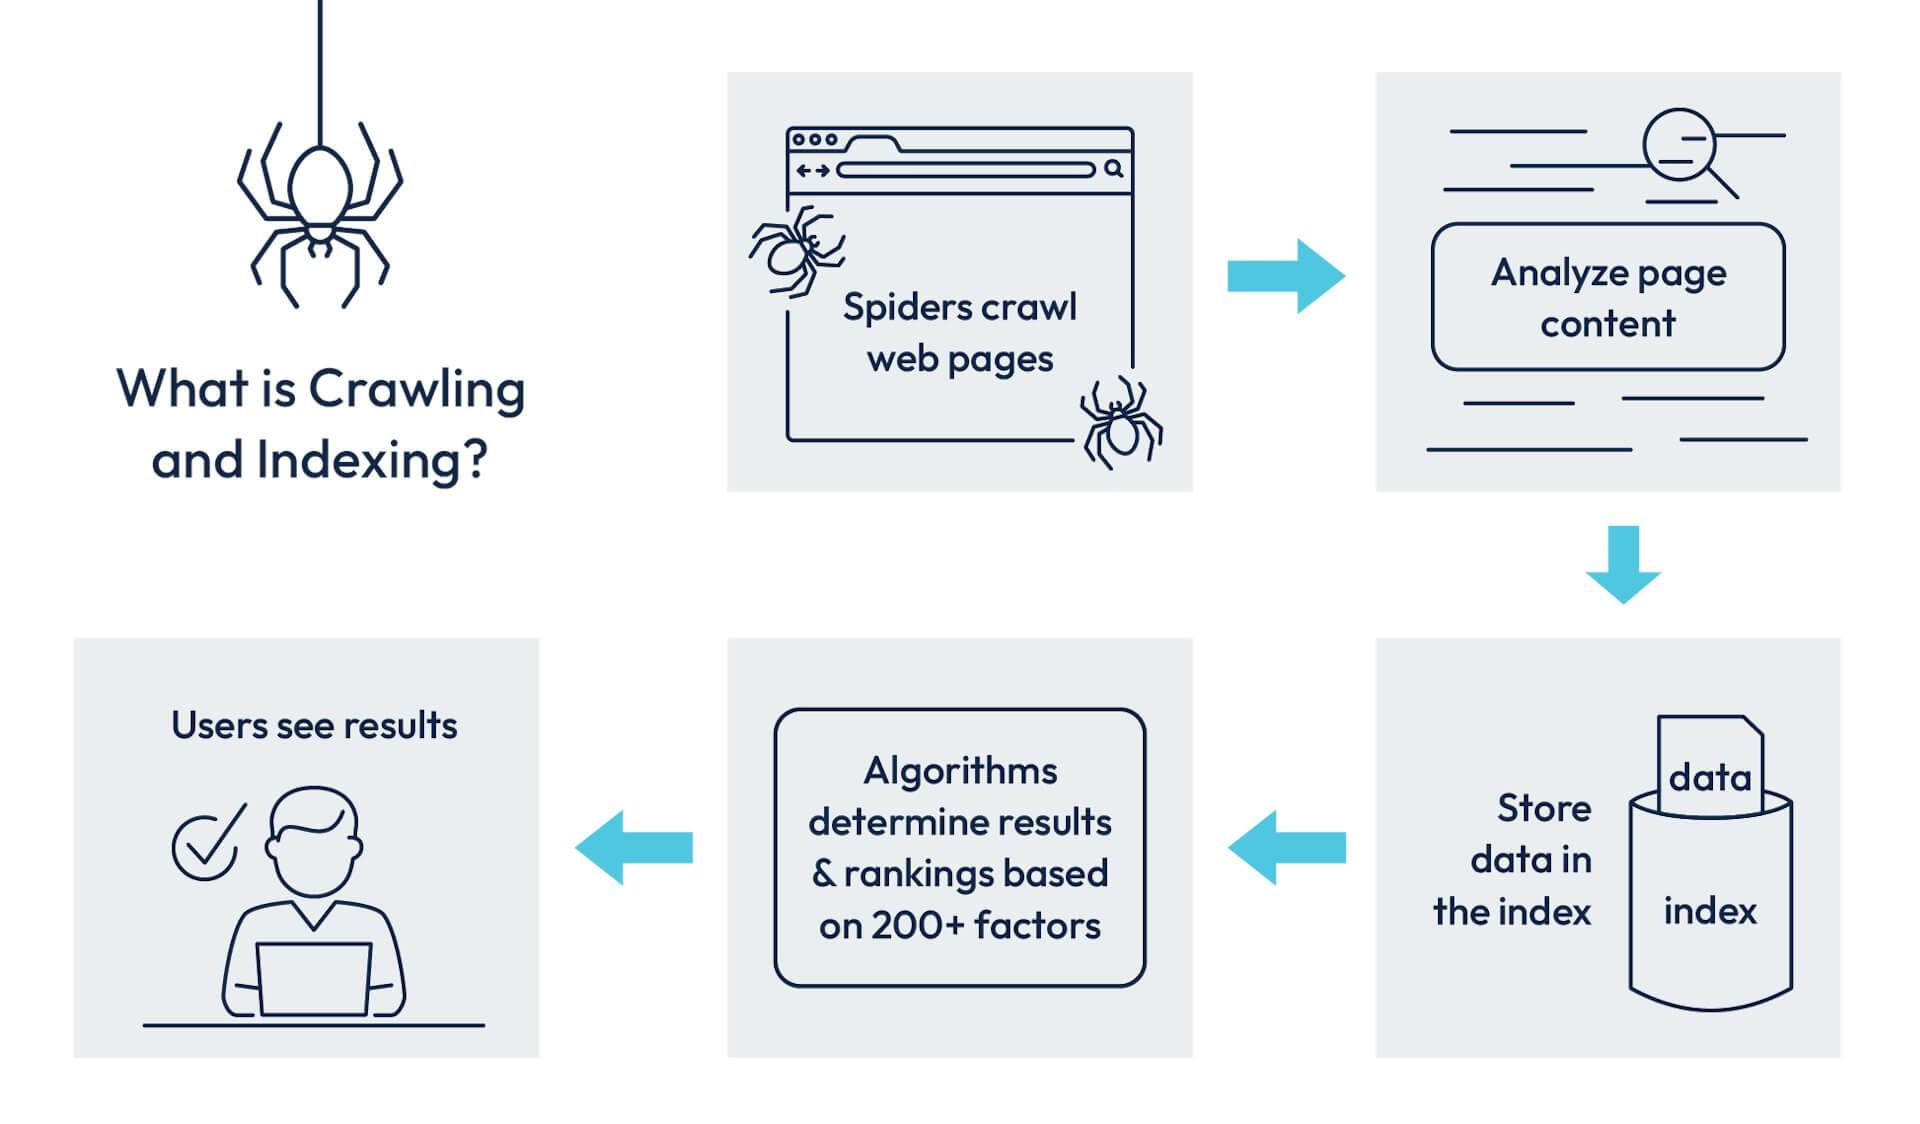
A traditional crawler treats every URL as a potential source, crawling depth‑first or breadth‑first until it’s exhausted. A list crawler, by contrast, starts with a predefined set of endpoints and repeatedly polls them at configurable intervals. This narrow scope means less bandwidth, lower server load, and a clearer picture of the data you actually need for real‑time dashboards.
Why List Crawlers Matter for Real‑Time Analytics
Real‑time analytics thrives on three pillars: speed, relevance, and reliability. List crawlers hit each one squarely.
- Speed. By limiting the crawl to known lists, the system can fetch updates in seconds rather than minutes.
- Relevance. Since the inputs are curated, the downstream processing pipeline skips unnecessary parsing and cleaning.
- Reliability. Re‑visiting the same endpoints on a tight schedule reduces the chance of missing transient changes, like flash sales or sudden price drops.
Benefit 1: Near‑Instant Data Ingestion
Because list crawlers repeatedly hit a small number of URLs, they can be set to run every few seconds. This cadence is especially valuable for monitoring stock levels, social‑media trending hashtags, or IoT sensor registries. The result is a data lake that feels less like a static archive and more like a live feed feeding dashboards in near‑real time.
Benefit 2: Granular, Up‑To‑Date Insights
When you only pull the rows you need—say, a CSV of daily exchange rates—you avoid the noise that comes from crawling entire pages. That granularity means analytics models can train on the most recent data points without being diluted by stale or irrelevant entries. In practice, this translates to more accurate forecasting and quicker anomaly detection.
Benefit 3: Cost Efficiency and Lower Overhead
Running a full‑site spider consumes bandwidth, storage, and compute cycles that many organizations simply can’t justify. List crawlers, on the other hand, operate within tight bandwidth caps and often fit on modest virtual machines. Companies report up to a 40 % reduction in cloud‑hosting costs when they replace broad crawls with focused list harvesting.
Benefit 4: Seamless Scalability
Because each list is an independent feed, you can add or retire sources without re‑architecting the entire pipeline. Need to monitor a new competitor’s price list? Just drop the URL into the crawler’s configuration file. The same modularity that makes micro‑services popular also applies here, letting data teams scale horizontally as their monitoring needs expand.
Benefit 5: Enhanced Data Quality and Deduplication
List crawlers often incorporate built‑in deduplication logic. Since the same endpoint is revisited regularly, the system can compare timestamps or hash values to flag unchanged rows. This reduces downstream duplication and ensures that analytics dashboards reflect only genuine changes, not re‑processed repeats.
Real‑World Use Cases
Consider an e‑commerce retailer that tracks competitor pricing across dozens of storefronts. By deploying list crawlers against each competitor’s public product feed, the retailer receives price updates within seconds of a change. Their pricing engine then recalculates optimal margins on the fly, keeping offers competitive without manual intervention.
Another example comes from a financial news aggregator that monitors dozens of RSS feeds for breaking headlines. A list crawler fetches each feed every 30 seconds, feeding a sentiment‑analysis model that alerts traders to market‑moving news before traditional newswire services catch up.
Getting Started with List Crawlers
If you’re new to the concept, begin with a single high‑impact list—perhaps a CSV of your top‑selling SKUs. Set the crawl interval based on how quickly you need updates (e.g., every 60 seconds for price tracking). Monitor the ingestion latency, then gradually add more lists, tweaking intervals to balance freshness against resource usage. Most open‑source frameworks, like Scrapy or Node‑Crawler, support list‑mode configurations out of the box.
FAQ
What’s the difference between a list crawler and a web scraper?
A web scraper extracts data from a single page or a set of pages, often on demand. A list crawler automates the repeated fetching of entire data sources (like CSV feeds) on a schedule, making it ideal for continuous, real‑time pipelines.
Can list crawlers handle authentication?
Yes. Modern crawlers can store API keys, OAuth tokens, or basic auth credentials, allowing them to pull from private endpoints securely.
Do list crawlers violate site terms of service?
Since they target publicly available feeds and respect robots.txt directives, they’re generally compliant. However, always review the source’s usage policy before automating access.
How do I ensure data freshness without overloading the source?
Start with a conservative interval (e.g., 5 minutes), then monitor HTTP 429 responses or server latency. Adjust intervals downward only if the source can handle the load, or implement exponential back‑off strategies.