How to Access Hacker News with Python: A Simple API Guide
If you’ve ever wanted to pull the latest stories from Hacker News without opening a browser, Python makes it a breeze. The official Firebase‑backed API is lightweight, public, and perfect for quick scripts or larger data‑driven projects. In this guide we’ll walk through installing the right library, fetching top stories, digging into individual items, and keeping your feed up‑to‑date—all with clear, minimal code.
Why Use the Hacker News API?
Hacker News isn’t just a news aggregator; it’s a real‑time pulse of tech culture. By tapping the API you can:
- Build custom dashboards that highlight topics you care about.
- Analyze posting trends for research or personal curiosity.
- Integrate story feeds into bots, newsletters, or mobile apps.
The endpoint is publicly available, requires no authentication, and returns JSON that maps directly onto Python data structures—no XML gymnastics, no OAuth hoops.
Getting Started: Install requests
The only external dependency you really need is requests, a friendly HTTP library that handles the heavy lifting of network calls. Open a terminal and run:
pip install requests
Once installed, you can import it and start talking to the API in seconds.
Access Hacker News with Python: Fetching Top Stories
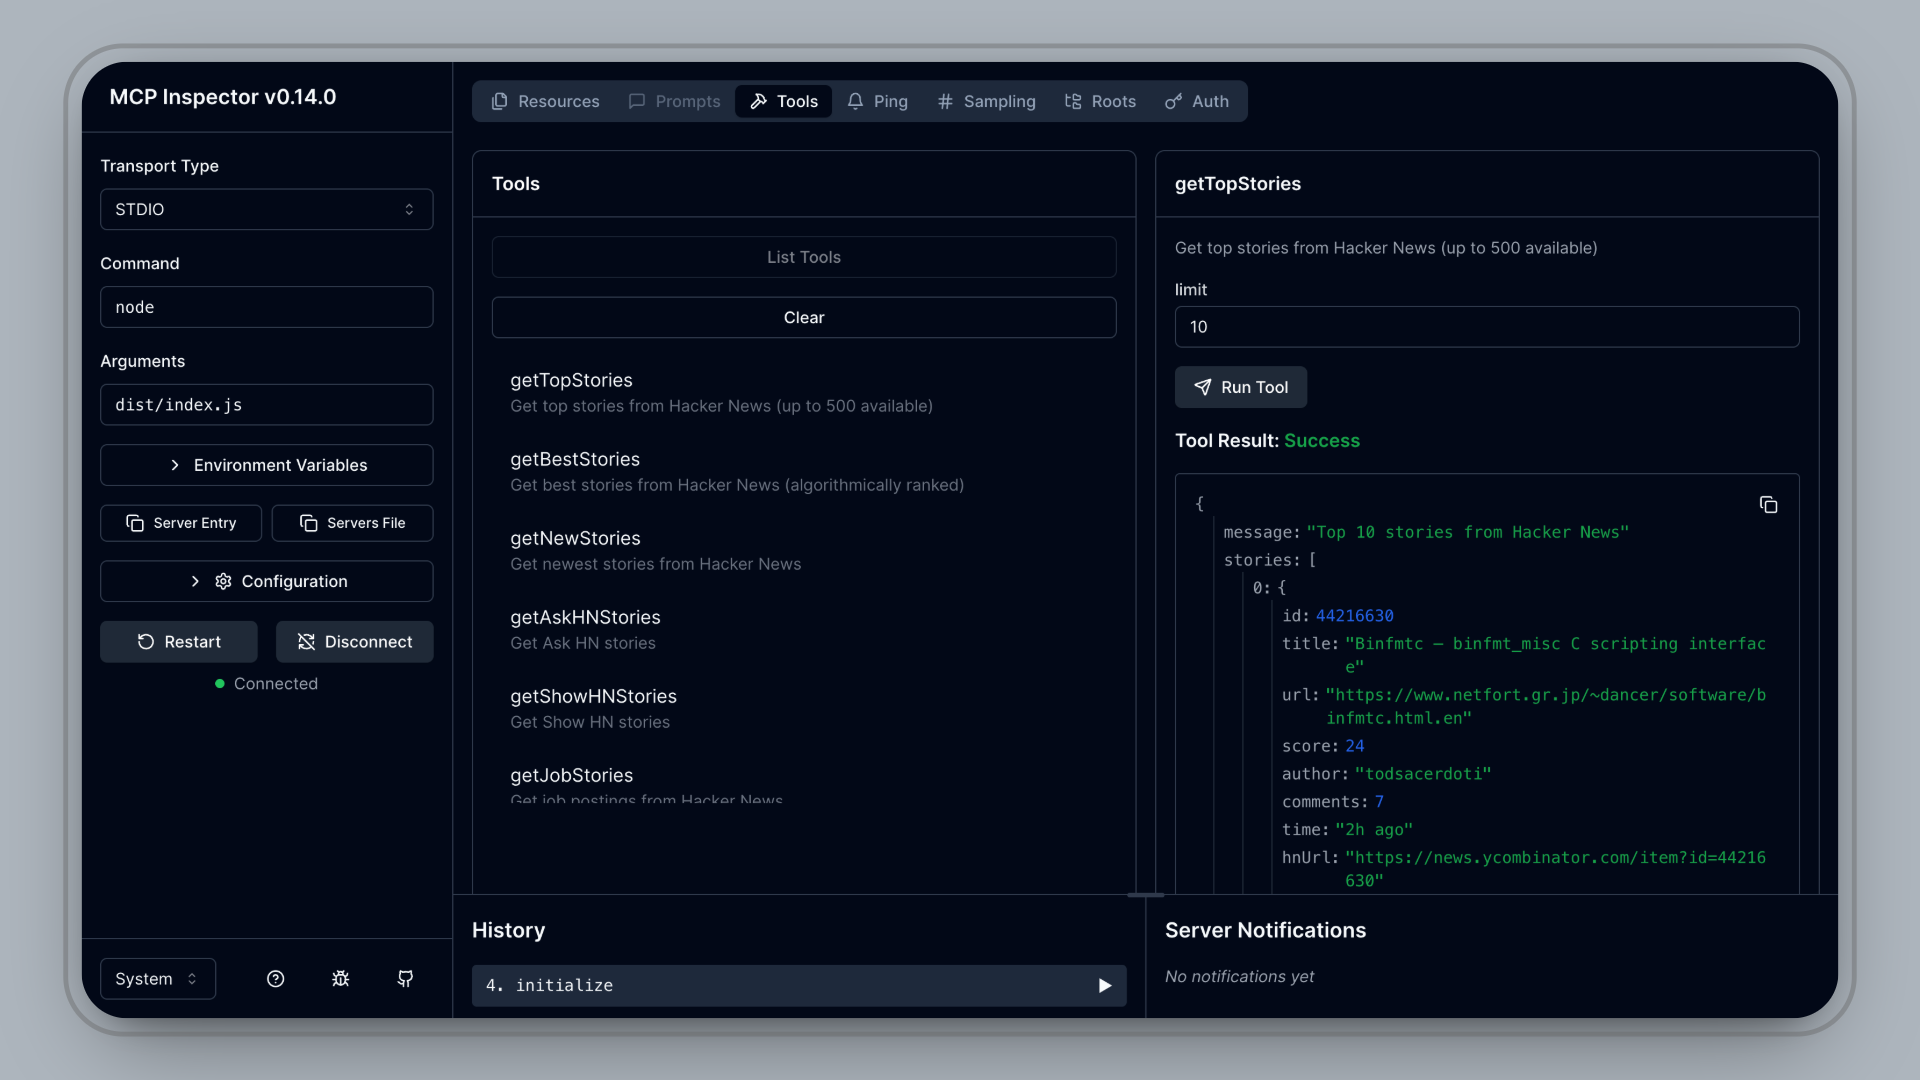
The first step is to retrieve the list of current top‑story IDs. The API exposes this as a single array at https://hacker-news.firebaseio.com/v0/topstories.json. Here’s a minimal snippet:
import requests
response = requests.get('https://hacker-news.firebaseio.com/v0/topstories.json')
ids = response.json()
‘ids’ now holds a list of integers, each representing a story. The list can be long—typically a few hundred entries—so you’ll probably want to slice it:
top_ten = ids[:10]
This gives you the ten most popular stories at the moment. From here you can pull the details of each story individually.
Pulling Individual Items
Every story, comment, or user profile lives at /v0/item/<id>.json. Replace <id> with the numeric ID you just fetched:
story_id = top_ten[0]
url = f'https://hacker-news.firebaseio.com/v0/item/{story_id}.json'
story = requests.get(url).json()
A story object contains fields such as title, url, score, and by (the author). For a quick preview you might print:
print(f\"{story['title']} ({story['score']} points) – by {story['by']}\")
Feel free to expand the loop to iterate over your chosen slice and collect the data into a list or pandas DataFrame for further analysis.
Handling Updates and Pagination
Hacker News updates frequently, and the top‑stories list can shift every few minutes. To keep your local copy fresh, schedule the fetch routine to run every 5‑10 minutes using cron (Linux/macOS) or Task Scheduler (Windows). A simple while‑loop with time.sleep(300) also works for quick prototypes.
If you need a broader view beyond the top stories, the API also offers newstories, beststories, and askstories. Each endpoint returns a similar ID array, so you can reuse the same fetching logic.
Common Pitfalls and How to Avoid Them
- Rate limits: The API is generous but not infinite. If you’re hammering it with hundreds of requests per second, you might see throttling. Batch your calls—fetch IDs once, then retrieve details in chunks.
- Missing fields: Not every item has a URL (think “Ask HN” posts). Guard against
KeyErrorby usingstory.get('url')or checking thetypefield first. - Stale data: Cached responses can linger in your session. Use
requests.get(..., headers={'Cache-Control': 'no-cache'})if you need the freshest snapshot. - Unicode quirks: Titles often contain non‑ASCII characters. Python 3 handles Unicode natively, but ensure your terminal or output file is set to UTF‑8 to avoid garbled text.
Putting It All Together: A Tiny Command‑Line Tool
Below is a concise script that prints the ten hottest stories, complete with titles, scores, and author names. Save it as hn_top.py and run python hn_top.py:
import requests
def fetch_top(n=10):
ids = requests.get('https://hacker-news.firebaseio.com/v0/topstories.json').json()[:n]
stories = []
for sid in ids:
data = requests.get(f'https://hacker-news.firebaseio.com/v0/item/{sid}.json').json()
stories.append(data)
return stories
for s in fetch_top():
print(f\"{s['title']} ({s['score']} pts) – by {s['by']}\")
This tiny utility demonstrates the core workflow and can be expanded with arguments for story count, output format (JSON, CSV), or even a simple Flask API of your own.
FAQ
Q: Do I need an API key to use the Hacker News API?
A: No. The endpoint is openly accessible; just be mindful of respectful request rates.
Q: Can I fetch comments for a story?
A: Yes. The story object includes a kids list of comment IDs. Query each ID with the same /item/<id>.json pattern to retrieve comment text, author, and timestamp.
Q: Is there a Python wrapper library I should use?
A: Several community packages exist (e.g., hackernews on PyPI), but the raw requests approach keeps dependencies low and mirrors the API directly.
Q: How can I store the data for later analysis?
A: Convert the list of story dictionaries to a pandas DataFrame and export to CSV, SQLite, or any format you prefer. The JSON structure maps cleanly to tabular columns.