Mastering Precision, Recall & Accuracy With Scikit‑Learn
Why These Three Numbers Matter
When you first see a confusion matrix, the terms precision, recall, and accuracy can feel like jargon from a different language. In reality, they are just three lenses through which a model’s performance is examined. Precision tells you how many of the items you flagged as positive are actually correct, while recall reveals how many of the real positives you managed to capture. Accuracy, the most familiar metric, measures the overall fraction of right predictions, regardless of class balance. Understanding these nuances is the first step toward using scikit‑learn’s metrics module effectively.
How scikit‑learn Computes Each Metric
Behind the scenes, scikit‑learn’s precision_score, recall_score, and accuracy_score functions translate raw predictions into the numbers you see on your dashboard. They all start from the same four counts: true positives (TP), false positives (FP), true negatives (TN), and false negatives (FN).
- Precision = TP / (TP + FP). If you’re predicting spam emails, a high precision means the few messages you label as spam are rarely legitimate.
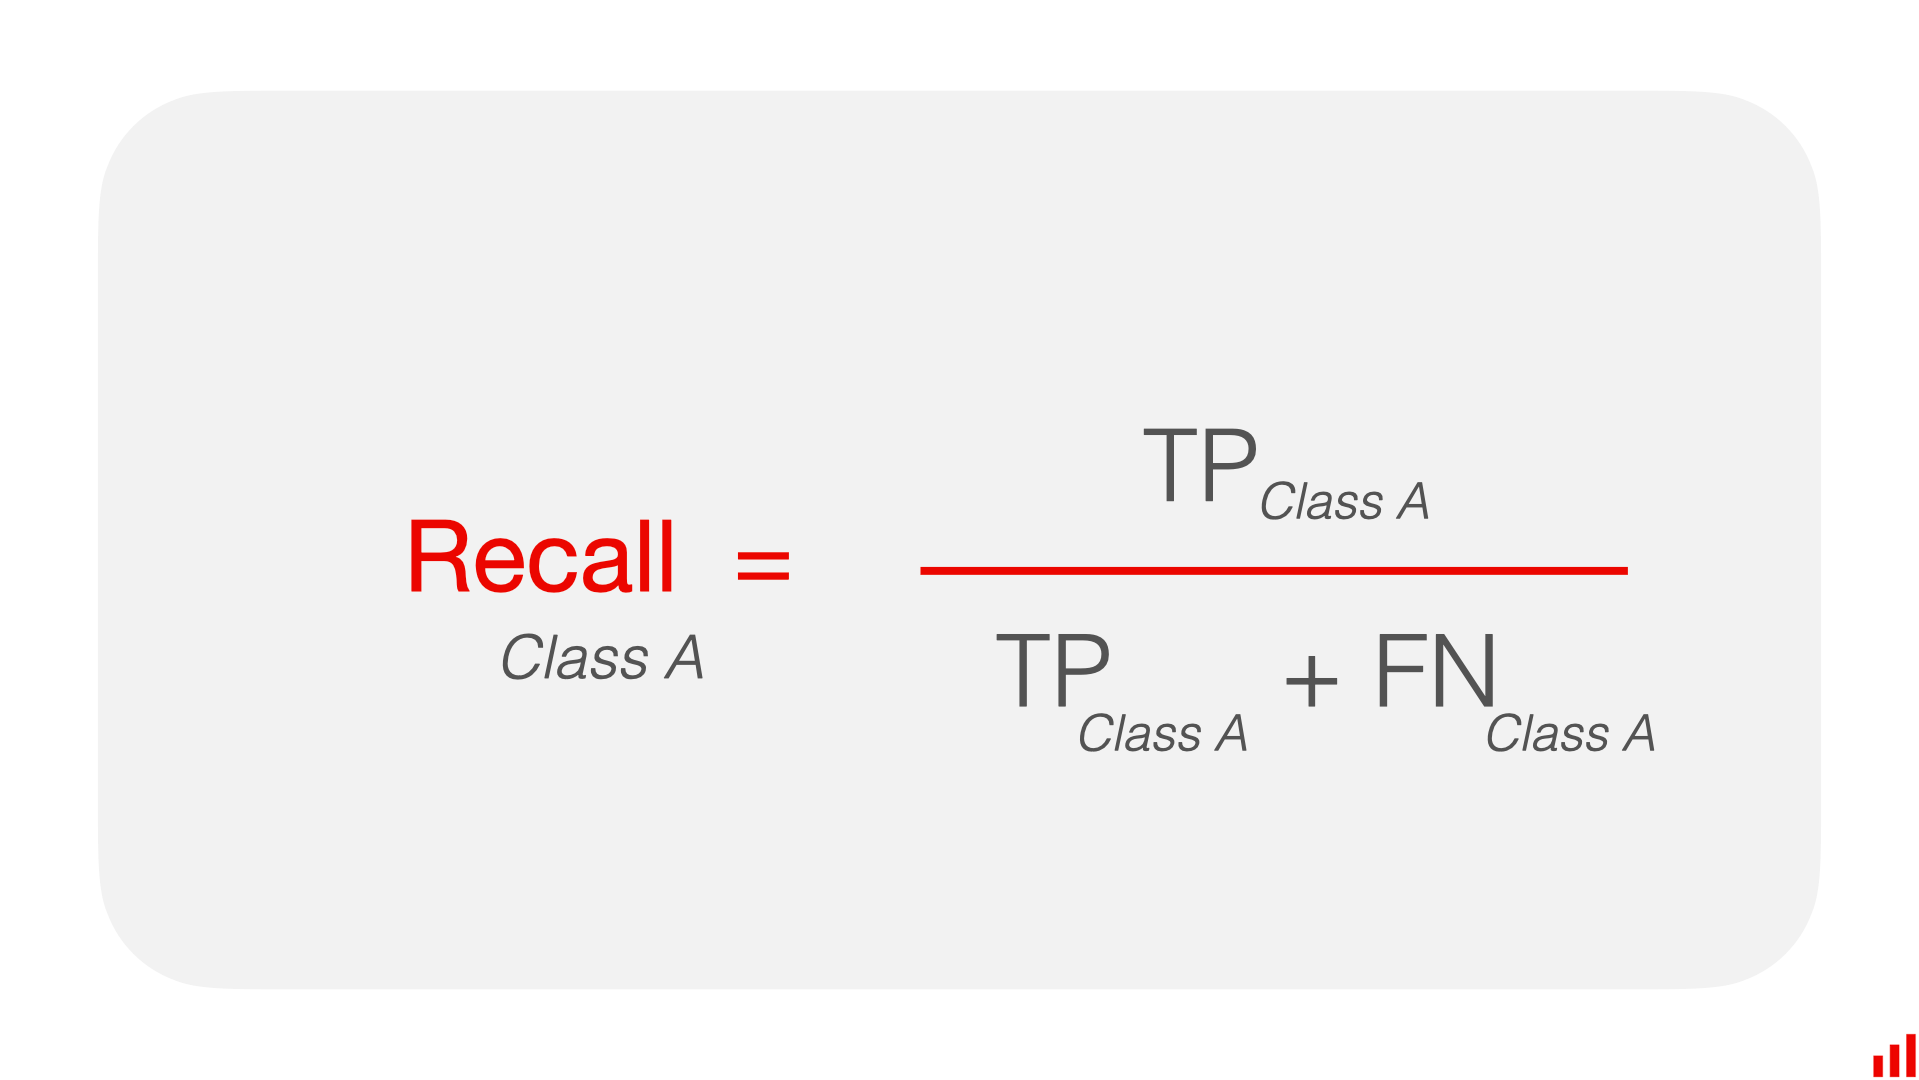
- Recall = TP / (TP + FN). In the same spam filter, high recall ensures you catch most of the actual junk, even if a few good emails slip through.
- Accuracy = (TP + TN) / (TP + FP + TN + FN). This aggregates correct predictions across both classes, which can be misleading when one class dominates.
The functions accept optional arguments like average='binary' or average='macro' to handle multi‑class scenarios, and zero_division to decide what to return when the denominator is zero.
When Precision Should Take the Lead
Imagine a medical diagnosis tool for a rare disease. A false positive might cause unnecessary anxiety, but a false negative could delay life‑saving treatment. In such high‑stakes settings, you often want to maximize precision: you’d rather flag fewer patients, but be confident those flagged truly have the disease. In scikit‑learn, you can push precision higher by tweaking the decision threshold on your classifier’s probability outputs, then re‑evaluating with precision_score.
When Recall Is the Priority
Conversely, consider a security system that scans network traffic for intrusions. Missing an actual breach (a false negative) could be catastrophic, while investigating a few false alarms is tolerable. Here, recall becomes the star metric. You can raise recall by lowering the classification threshold, then verify the trade‑off with recall_score. Remember, boosting recall almost always drags precision down—a classic balancing act.
Why Accuracy Can Be Deceiving
Accuracy looks clean on paper, but it can mask problems in imbalanced datasets. Suppose you have 1,000 emails, 950 of which are legitimate and only 50 are spam. A naïve model that labels everything as legitimate would achieve 95 % accuracy, yet it would be useless for spam detection. In such cases, precision and recall (or the combined F1 score) give a far more honest picture of performance.
Bringing It All Together With the F1 Score
The F1 score is the harmonic mean of precision and recall, offering a single number that balances the two. Scikit‑learn’s f1_score function automatically handles binary and multi‑class settings. Because it penalizes extreme imbalances between precision and recall, the F1 is especially handy when you need a quick, comparative snapshot across several models.
Practical Tips for Real‑World Projects
- Start with a confusion matrix (
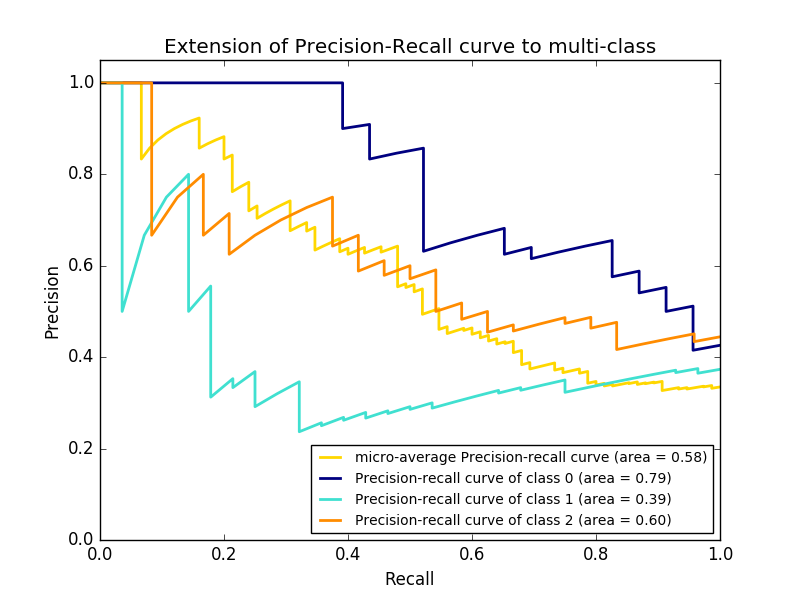
confusion_matrix) to see the raw counts before diving into derived metrics. - Plot precision‑recall curves (
precision_recall_curve) to visualize how thresholds affect both metrics. - When dealing with multi‑class problems, use
average='weighted'to account for class frequencies, oraverage='macro'if you want each class to count equally. - Document the chosen threshold and the rationale behind prioritizing one metric over another; this transparency helps stakeholders trust the model.
- Combine metric analysis with domain knowledge—no statistical number can replace an understanding of what a false positive truly costs in your application.
Frequently Asked Questions
Q: Can I rely on accuracy for a binary classification problem?
A: Only if the classes are roughly balanced. With skewed data, accuracy may hide poor detection of the minority class, so always check precision and recall as well.
Q: How does scikit‑learn handle undefined precision or recall?
A: If the denominator is zero (e.g., no predicted positives), the function returns 0 by default, but you can change this behavior with the zero_division parameter.
Q: Should I always report the F1 score?
A: The F1 is useful when you need a single performance figure, but it discards information about the individual precision and recall values. Reporting all three gives a fuller story.
Q: Is there a way to optimize the threshold automatically?
A: Yes. Use roc_curve or precision_recall_curve to find the point that maximizes a chosen metric, then set the classifier’s decision_function or predict_proba cutoff accordingly.