Spotting Fake News Like a Pro: The Deep Learning Revolution
Deep Learning Spotting Fake News Like A Pro has moved from academic curiosity to everyday newsroom weaponry. In an era where misinformation spreads faster than viral videos, the ability to flag deceptive content instantly can save reputations, protect elections, and safeguard public health. This article walks through the core technologies, real‑world deployments, and practical steps for anyone looking to harness deep learning for fact‑checking.
Deep Learning Spotting Fake News Like A Pro: What It Means Today
The phrase captures more than a technical trick—it represents a paradigm shift. Traditional rule‑based filters rely on keyword matching or simple heuristics, which attackers can easily bypass. Deep learning, by contrast, learns nuanced patterns across millions of news articles, detecting subtle signals that humans might miss.
Why Traditional Filters Fall Short
Early fake‑news systems built on keyword lists or Boolean logic struggled with context. A sentence like “The virus is real” could be a headline or a rebuttal. Human editors, while adept, cannot scale to the volume of daily posts. Machine learning models that use shallow features also fail to capture sarcasm, cultural references, or evolving jargon.
The Rise of Transformer Models
Transformers, especially architectures like BERT, RoBERTa, and GPT‑based variants, have set new accuracy benchmarks for language tasks. Their bidirectional attention mechanisms enable the model to understand a word’s meaning in relation to the entire sentence, which is crucial for distinguishing legitimate claims from fabricated ones. Fine‑tuning a pre‑trained transformer on a labeled fake‑news corpus yields performance that often rivals seasoned fact‑checkers.
Key Techniques in Fake News Detection
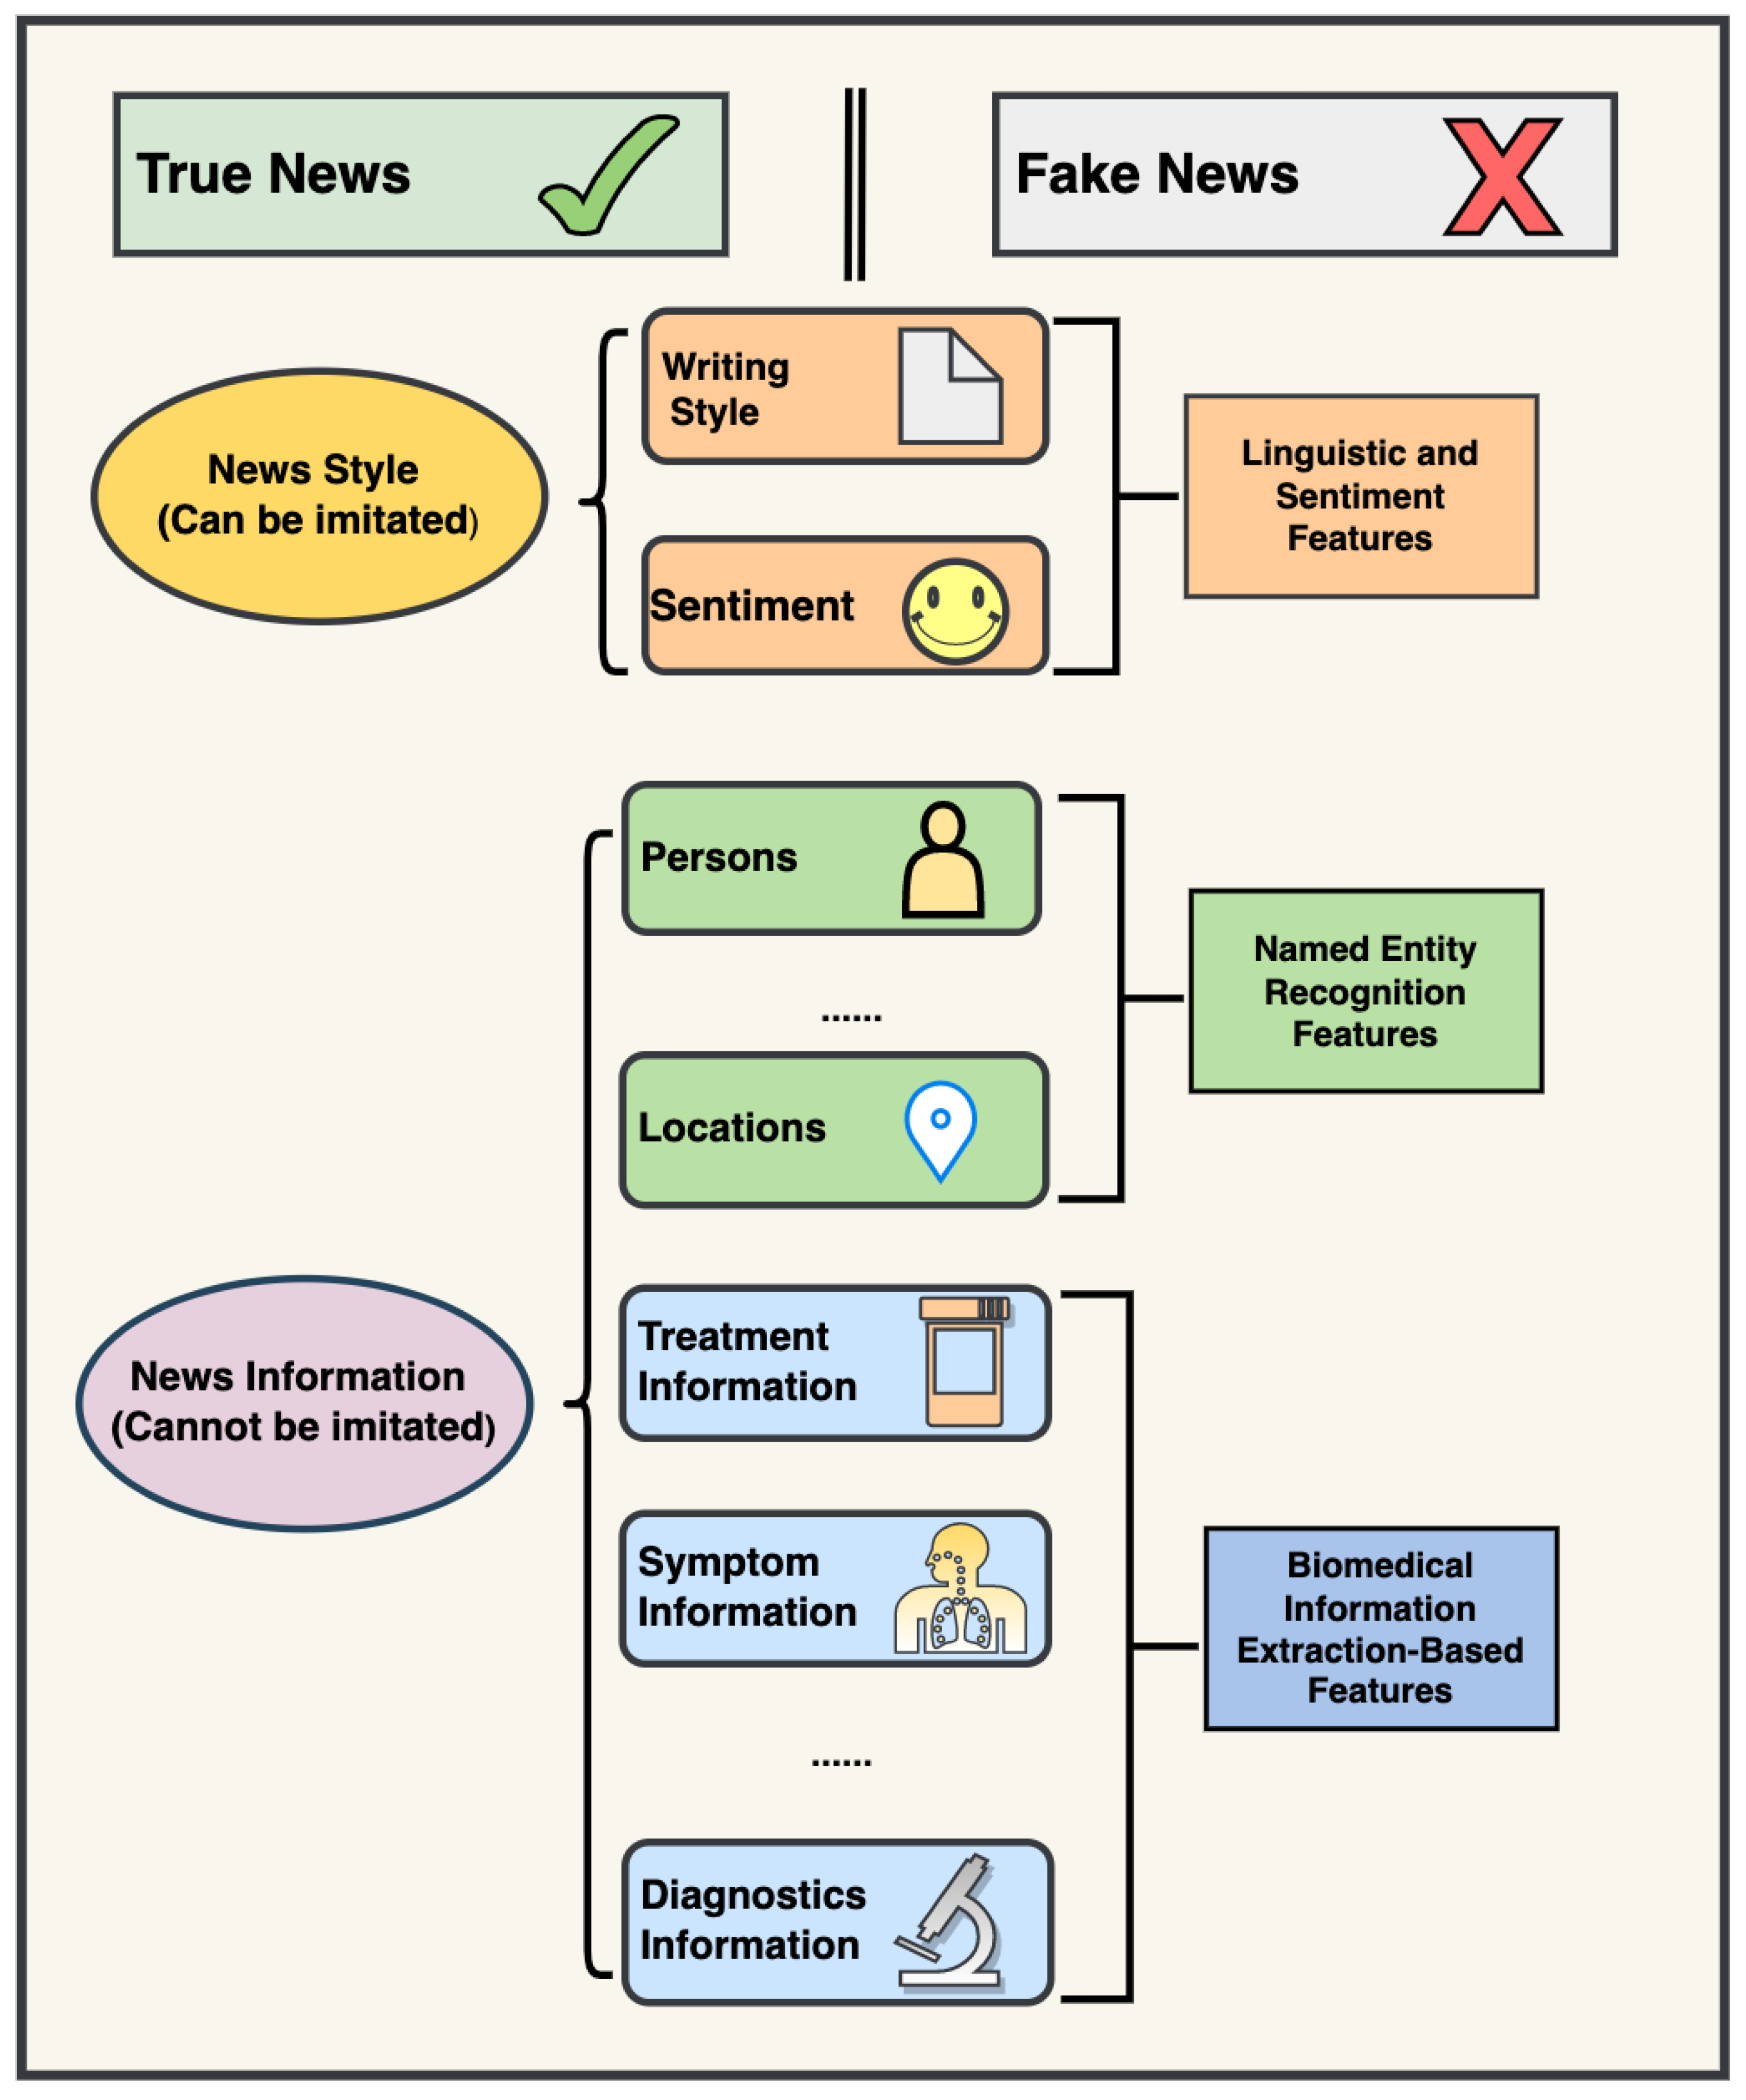
- Textual Analysis – Sentiment, readability scores, and keyword density are baseline features. When combined with transformer embeddings, they become powerful predictors.
- Stylometry – Writing style, punctuation patterns, and sentence length distribution can reveal an author’s typical habits, helping to flag suspicious sources.
- Contextual Embeddings – By converting entire articles into dense vectors, models capture semantic similarity, making it easier to spot re‑used fabrications across different headlines.
- Multimodal Analysis – Images, videos, and embedded links are cross‑checked against known databases, reducing the chance that a picture is paired with a false caption.
- Graph‑Based Features – Social media propagation patterns, user interaction networks, and citation graphs provide clues about the article’s authenticity.
Real‑World Applications and Partnerships
Several tech giants have integrated deep‑learning fake‑news detection into their platforms. For example:
- Facebook’s “News Feed Quality” team employs transformer classifiers to surface potentially misleading posts.
- Twitter uses a multimodal model that flags tweets with fabricated facts before they spread.
- News organizations like The New York Times and Reuters run internal bots that pre‑screen user‑generated content, allowing human editors to focus on nuanced judgment calls.
Academic‑industry collaborations have also produced open datasets such as LIAR, FakeNewsNet, and the COVID‑19 misinformation corpus, enabling researchers to benchmark and improve algorithms.
Limitations and Ethical Considerations
Even the most advanced models are not foolproof. Adversaries can employ adversarial attacks—adding benign text that fools the model while preserving the lie. Bias can creep in when training data overrepresents certain topics or political viewpoints. Moreover, automatic flagging can unintentionally suppress minority voices if not carefully calibrated.
Transparency is vital. Stakeholders should disclose the model’s decision rationale, the uncertainty level, and the possibility of false positives. Continuous human oversight remains the safety net that balances speed with correctness.
Getting Started: How to Build Your Own Model
Below is a practical roadmap for developers and data scientists interested in building a fake‑news detector.
- Collect Data – Combine labeled datasets (e.g., FakeNewsNet) with your own curated articles. Ensure diversity across domains and languages.
- Preprocess Text – Clean HTML, tokenize, and remove stop words. Use a tokenizer that aligns with your transformer library.
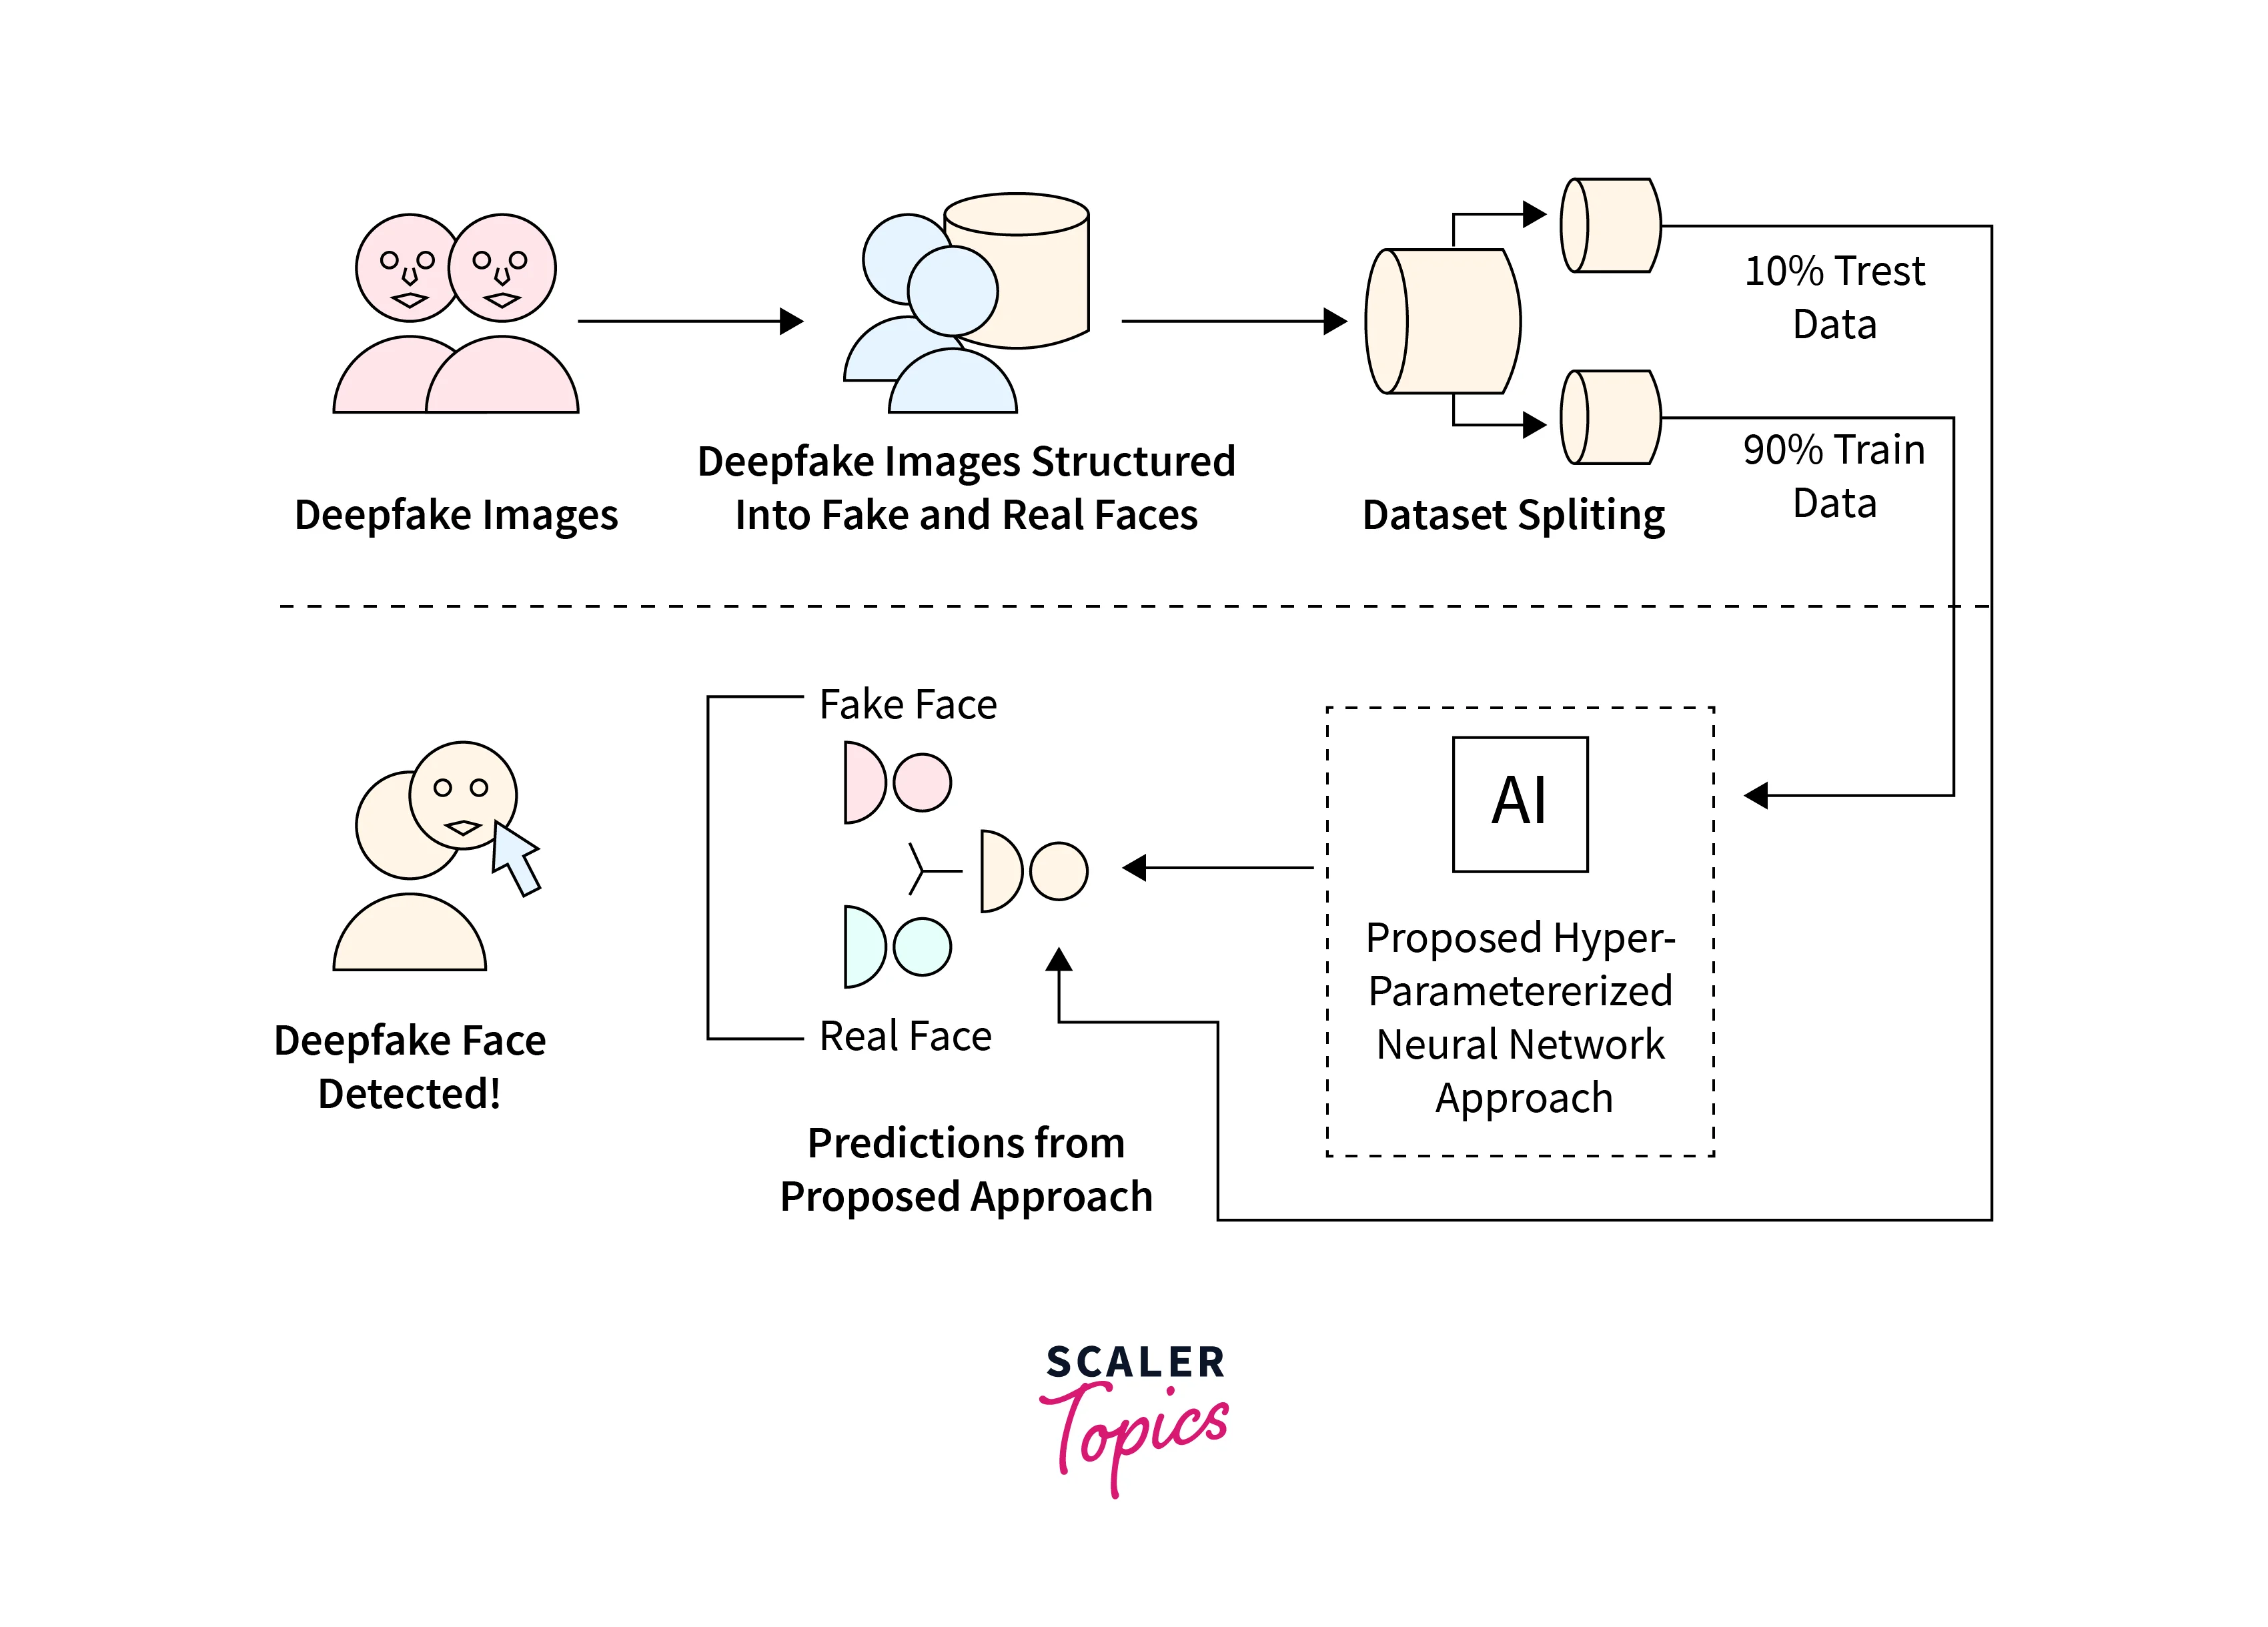
- Fine‑Tune a Transformer – Load a base model (BERT, RoBERTa) and add a classification head. Train on 80 % of your data, validate on 10 %, test on 10 %.
- Evaluate – Use precision‑recall curves and F1‑score. Check for class imbalance and adjust thresholds accordingly.
- Deploy – Expose the model via a REST API. Integrate with a content‑management system or browser extension for real‑time checks.
- Monitor – Collect feedback from users and retrain periodically to adapt to evolving misinformation tactics.
Open‑source libraries like Hugging Face’s Transformers and fast.ai simplify many of these steps, making deep‑learning fake‑news detection accessible to non‑experts.
FAQs
Q1: Can deep learning completely replace human fact‑checkers?
A1: No. While deep learning can flag suspicious content quickly, human judgment remains essential for interpreting context, assessing intent, and making final editorial decisions.
Q2: How do models stay updated as new fake news trends emerge?
A2: Continuous retraining on fresh data, coupled with active learning where uncertain cases are reviewed